This research introduces APEX, a post-hoc method for explaining what a pre-trained audio classifier, including deepfake detectors, actually relied on to reach its decision. Authored by Resemble AI's Piotr Kawa alongside researchers at Wrocław University of Science and Technology, the IDEAS Research Institute, and Jagiellonian University. Currently an arXiv preprint, not yet peer reviewed.
Overview
A detector that says "98% fake" without saying why is an increasingly hard thing to trust, and legally deploy. Regulations like the EU AI Act are pushing toward requiring that high-stakes automated decisions be explainable, not just accurate. Deep neural audio classifiers often operate on spectrograms, which represent audio as a time-frequency image. To explain decisions made on them most tools borrow directly from image recognition, treating a spectrogram like a photograph and drawing a heatmap over it. That approach quietly ignores something basic about audio: the time axis and the frequency axis mean completely different things, one is "when," the other is "at what frequency" and treating them as interchangeable, the way two spatial dimensions in a photo are, loses meaning.
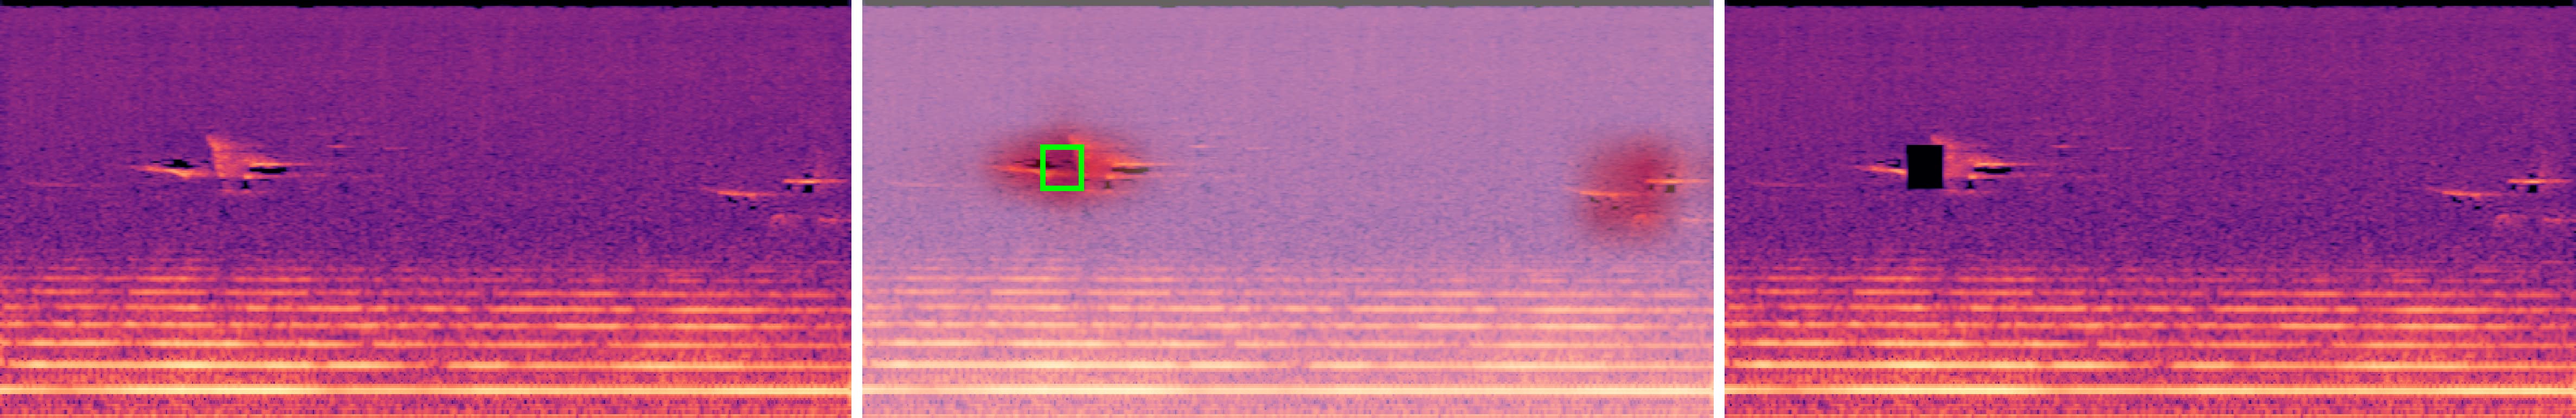
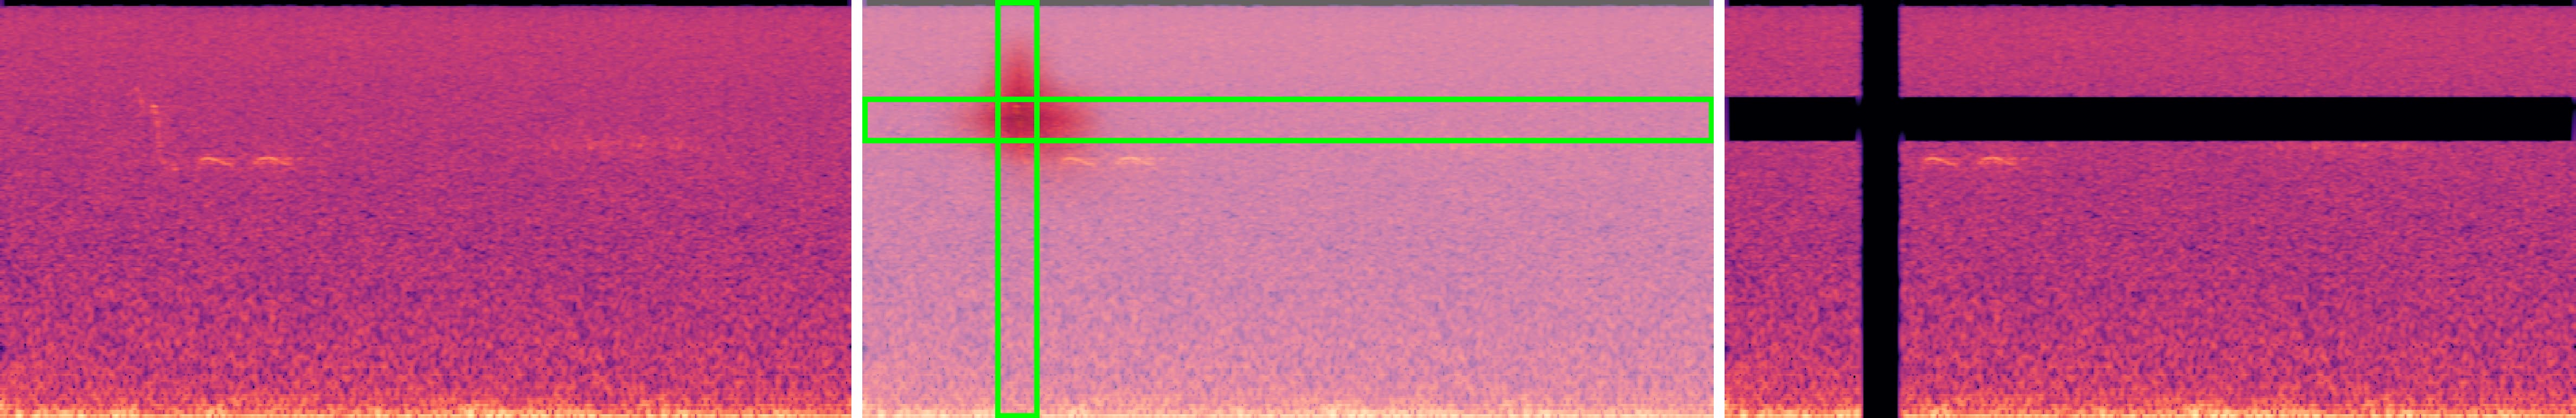
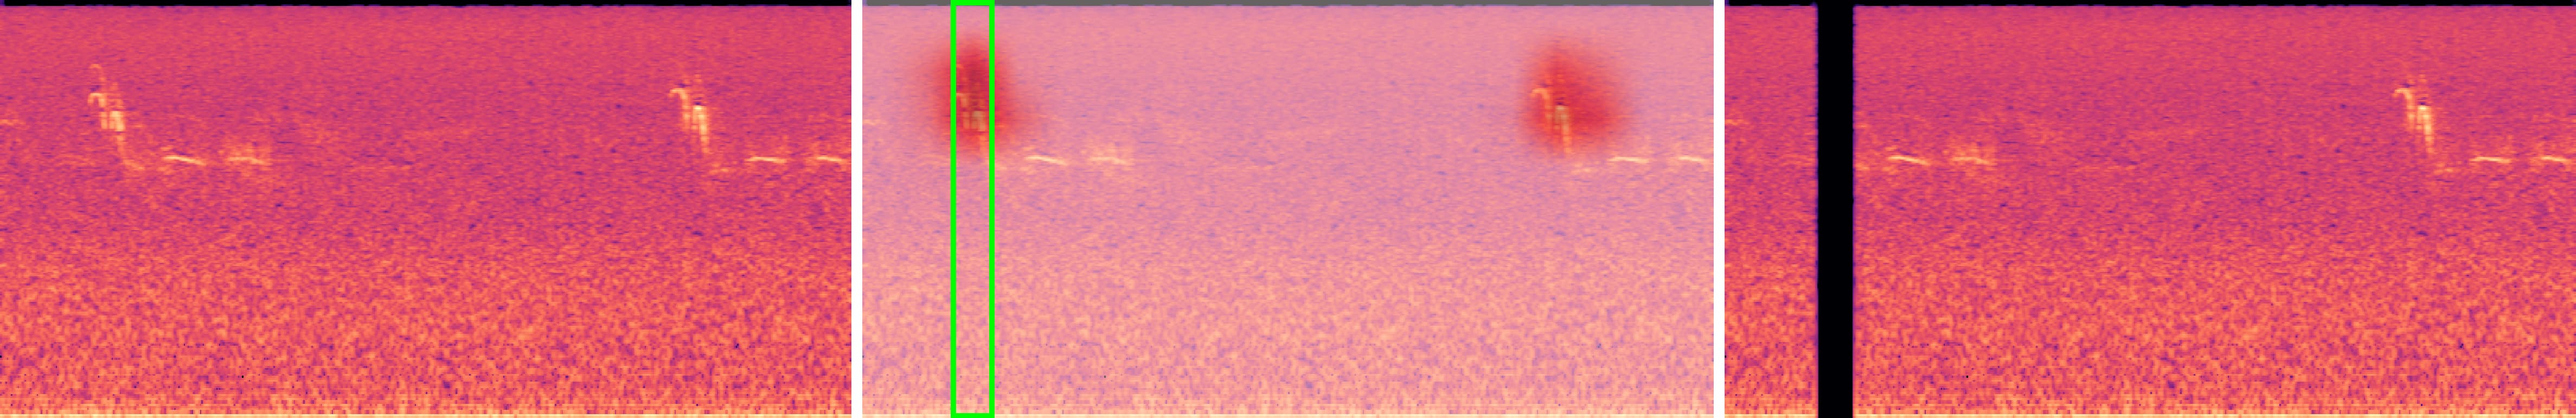
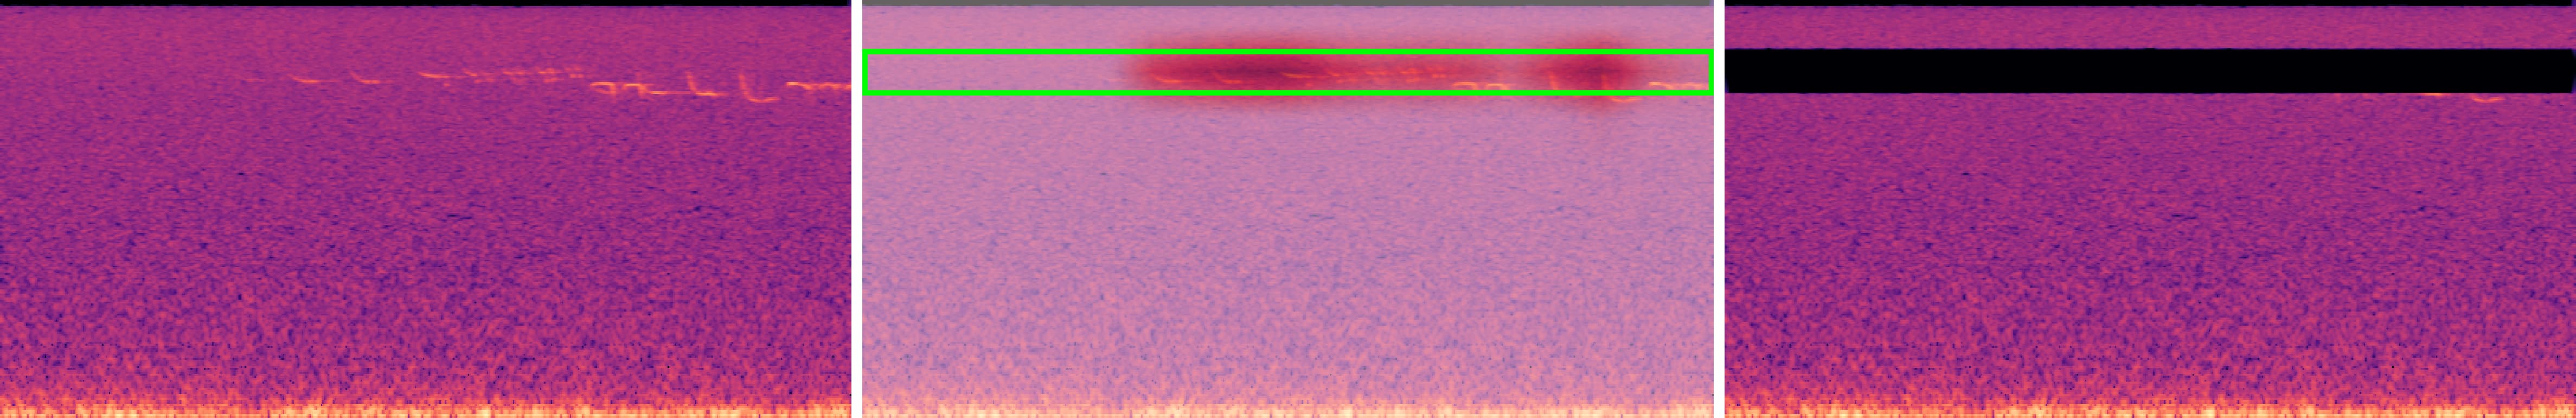
APEX is built around that distinction. It works with already-trained audio classifiers, deepfake detectors or otherwise, and doesn't retrain or modify it at all: it's mathematically guaranteed to produce the exact same predictions as before. What it adds is a way to look inside the model's decision with one of four available explanation types depending on the kind of sound, whether the decision hinged on a brief transient event, a pattern over time, a specific frequency band, or some balance of both, and then shows training examples that share that acoustic signature - so called prototypes.
Download the full research PDF on arXiv.
Methodology
Most classifiers pack their internal understanding of a sound into sets of numbers (feature vectors) that are usually tangled up, a single acoustic idea, like "this frequency range has this kind of buzz", gets smeared across many different internal channels rather than living in one clean, identifiable place. APEX introduces a Disentanglement Module, a mathematical transformation between the model's feature-extraction layers and its final decision layer that re-organizes those internal channels into cleaner, more separable ones. The clever part is that this transformation is invertible, so its effect gets exactly undone before the final decision is made, meaning the model's actual output never changes, only what happens in between becomes easier to inspect without sacrificing the original performance of the network.
Once the internal space is reorganized, APEX defines four different ways to ask "what mattered here," matched to different types of sound:
- a brief, localized event like a click gets a square-based explanation,
- a rhythm or pattern that unfolds over time gets a time-based one,
- a steady tone or spectral signature gets a frequency-based one,
- and anything needing both gets a time-frequency hybrid.
For each, APEX also points out examples from the training data (so called prototypes) that most similarly share the same properties.
Results
The first result is the guarantee working as designed: across every training configuration tested, on both the deepfake-detection task and the bird-classification task, APEX's classifier produced identical error rates to the original, unmodified model. Interpretability didn't cost performance and does not require any additional training. AudioProtoPNet, the established prototype-based baseline, doesn't offer this: its scores drift in both directions – better on some types of data and regions, worse on others – because introducing explainability using that method leaves a mark on the network.
To check that these explanations are actually meaningful and not just plausible-looking, the team ran a masking test: take the exact region APEX says mattered, black it out, and see how much the classifier's performance drops. They compared that against masking a random region of the same size and shape. If APEX's explanations are real, masking them should hurt performance more than masking at random, and if they're not, it shouldn't matter which region gets masked. On the bird-classification task, masking a random region of the input barely hurt performance (accuracy dropped only slightly, from a class-mean average precision of 0.32 to 0.27). But masking the exact region APEX identified as important caused a much sharper drop, down to 0.17, roughly double the damage from an equally-sized random mask. The same pattern held on the audio deepfake detection task: APEX-guided masking consistently raised error rates more than random masking across the four extraction schemes. That gap is the actual evidence that APEX is pointing at real decision-relevant acoustic structure, not just drawing a plausible-looking picture..
Why this matters: A detection system that can only say "fake" or "real" with a confidence score, and nothing else, is a harder sell in any regulated or high-stakes context, and a harder thing to debug when it's wrong. Being able to show which specific time window or frequency band drove a decision, and back it up with real comparable examples, changes an audio classifier from a black box into something a compliance team, an auditor, or an engineer can actually inspect. That APEX does this without touching the underlying model's accuracy at all is what makes it practical rather than theoretical: nobody has to choose between a detector that performs well and one that can explain itself.
Limitations
- While APEX works with architectures based on convolutional neural networks, or Transformer-based encoders, the architectures it’s applied on must follow a specific structure by having a pooling layer followed by a single linear classification layer and operating on spectrogram inputs. It doesn't (yet) apply to arbitrary model architectures.
- The deepfake detection experiment used an academic classifier trained on the WaveFake benchmark, not Resemble's own production detector; these findings demonstrate the method; they don't directly characterize any specific commercial detector's explainability.
- The deepfake detection test set is English-only, single-speaker (LJSpeech) audio, and excludes one of WaveFake's eight fake-audio sources (a TTS-based one) for technical alignment reasons
How to cite this paper
APA Kawa, P., Howil, K., Borycki, P., Adamczyk, M., Spurek, P., & Syga, P. (2026). APEX: Audio prototype explanations for classification tasks. arXiv preprint arXiv:2605.10153.
BibTeX @article{kawa2026apex, title={APEX: Audio Prototype EXplanations for Classification Tasks}, author={Kawa, Piotr and Howil, Kornel and Borycki, Piotr and Adamczyk, Miłosz and Spurek, Przemysław and Syga, Piotr}, journal={arXiv preprint arXiv:2605.10153}, year={2026}
Sources
This is a curated subset, the full paper cites 42.
- Heinrich et al. AudioProtoPNet: An interpretable deep learning model for bird sound classification. Ecological Informatics, 87, 2025.
- Chen et al. This looks like that: deep learning for interpretable image recognition (ProtoPNet). NeurIPS, 2019.
- Selvaraju et al. Grad-CAM: Visual explanations from deep networks via gradient-based localization. ICCV, 2017.
- Ribeiro, Singh, and Guestrin. "Why should I trust you?": Explaining the predictions of any classifier (LIME). KDD, 2016.
- Gupta et al. Phoneme Discretized Saliency Maps for Explainable Detection of AI-Generated Voice. INTERSPEECH, 2024.
- Frank and Schönherr. WaveFake: A data set to facilitate audio deepfake detection. NeurIPS Datasets and Benchmarks Track, 2021.
- Rauch et al. BirdSet: A large-scale dataset for audio classification in avian bioacoustics. ICLR, 2025.
- Liu et al. A ConvNet for the 2020s (ConvNeXt). CVPR, 2022.
- Shen et al. On the reliability of feature attribution methods for speech classification. INTERSPEECH, 2025.
FAQs
Does making an audio deepfake detector explainable reduce its accuracy? No. APEX is mathematically guaranteed to preserve the original detector's exact predictions; in testing, error rates matched the unmodified baseline model exactly across every configuration.
How does APEX explain a detector's decision? It highlights the specific time window, frequency band, or combined time-frequency region that most influenced the decision, and surfaces real training examples that share that acoustic pattern, rather than a generic heatmap.
How do we know APEX's explanations are actually meaningful, not just plausible-looking? The researchers masked out the exact regions APEX flagged as important and re-ran the classifier; performance dropped significantly more than when masking random regions of the same size, confirming the flagged regions were genuinely load-bearing for the decision.